Insights
Technical deep dives, industry analysis, and perspectives on AI inference from the Infercom team.
Stop Chasing Determinism - A Practical Guide to LLM Consistency
Temperature, top_p, top_k and repetition_penalty explained - why temperature=0 is the riskiest setting for consistency, why batch size changes your output, and what gives you reliable LLM results.

Open-Weight AI Models: Why They're a Strategic Advantage
Open-weight models like Gemma and MiniMax power your AI applications - and they give you freedoms proprietary APIs can't. What open weight means, why it reduces lock-in, and how it keeps you in control of your data.
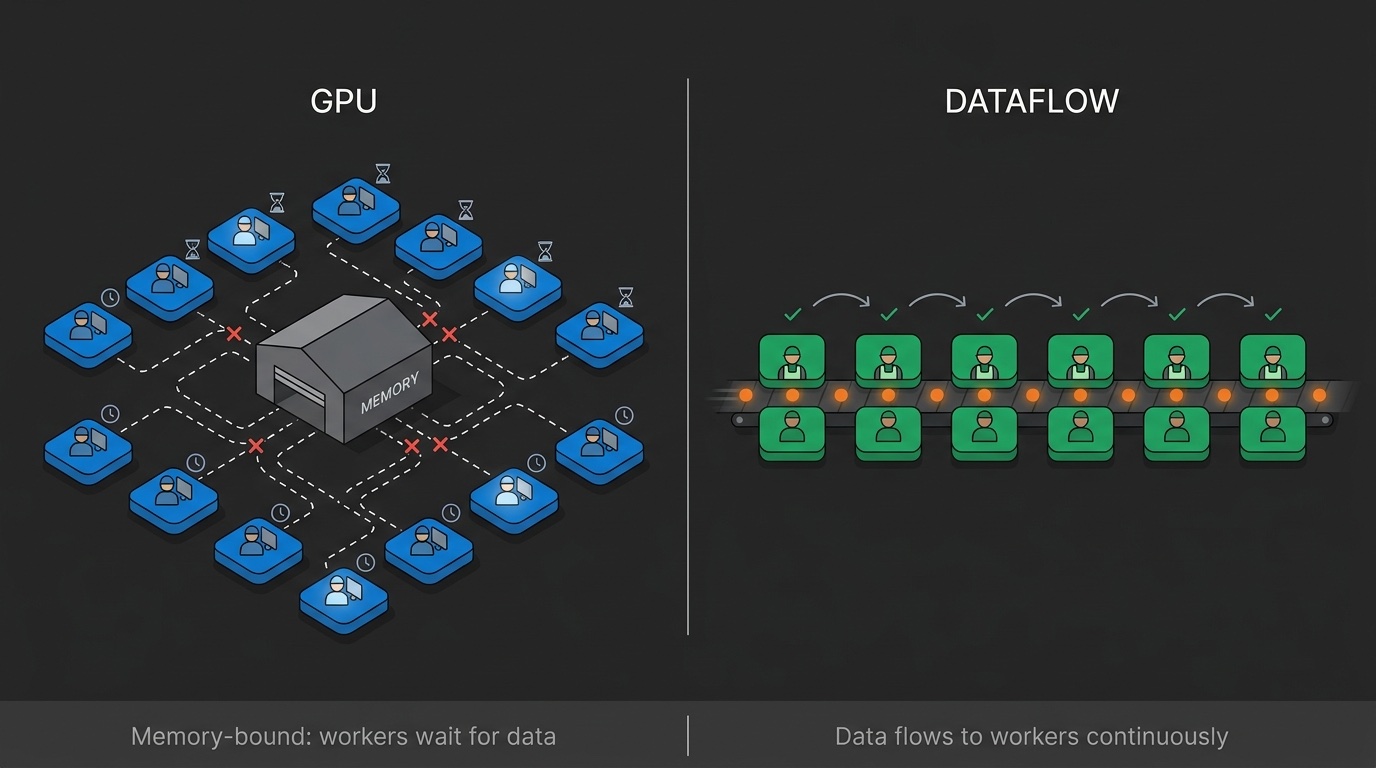
713 Tokens Per Second: The Architecture Behind Ultraspeed
Why dataflow architecture outperforms GPUs for LLM inference. Technical explanation of memory bottlenecks, spatial execution, and the decode problem.
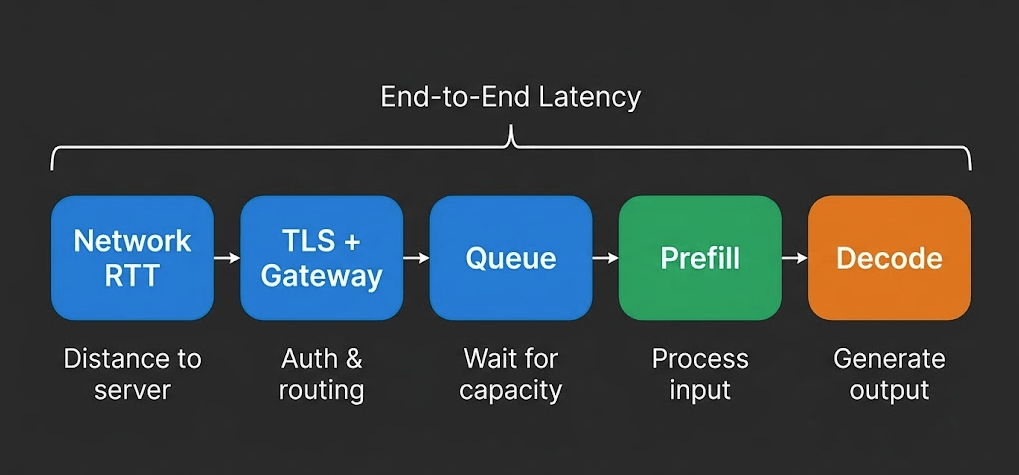
LLM Inference Speed Explained: TTFT, Throughput, and What Actually Matters
When one provider advertises 400 tok/s and another claims sub-200ms latency, they're measuring different things. Learn which metrics matter for your workload.
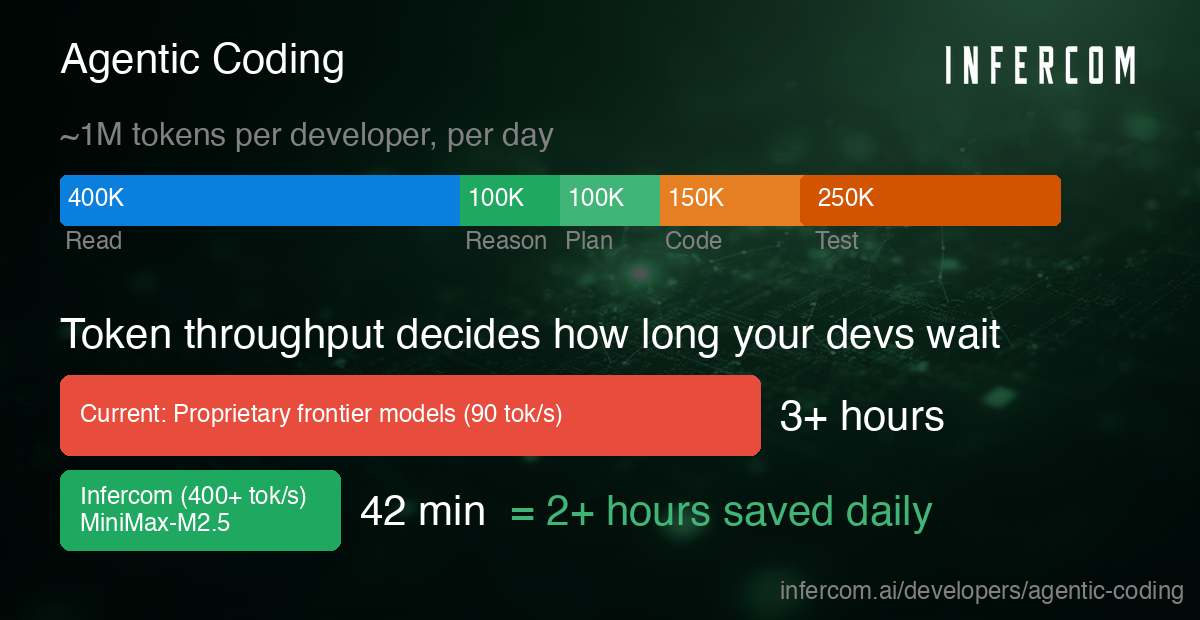
Inference Speed in Agentic Coding: Why Token Throughput Matters
Agentic coding tools consume 500K-2M tokens per developer per day. This article explains why inference speed matters and how to configure tools like Cursor, Cline, and Codex CLI for faster throughput.
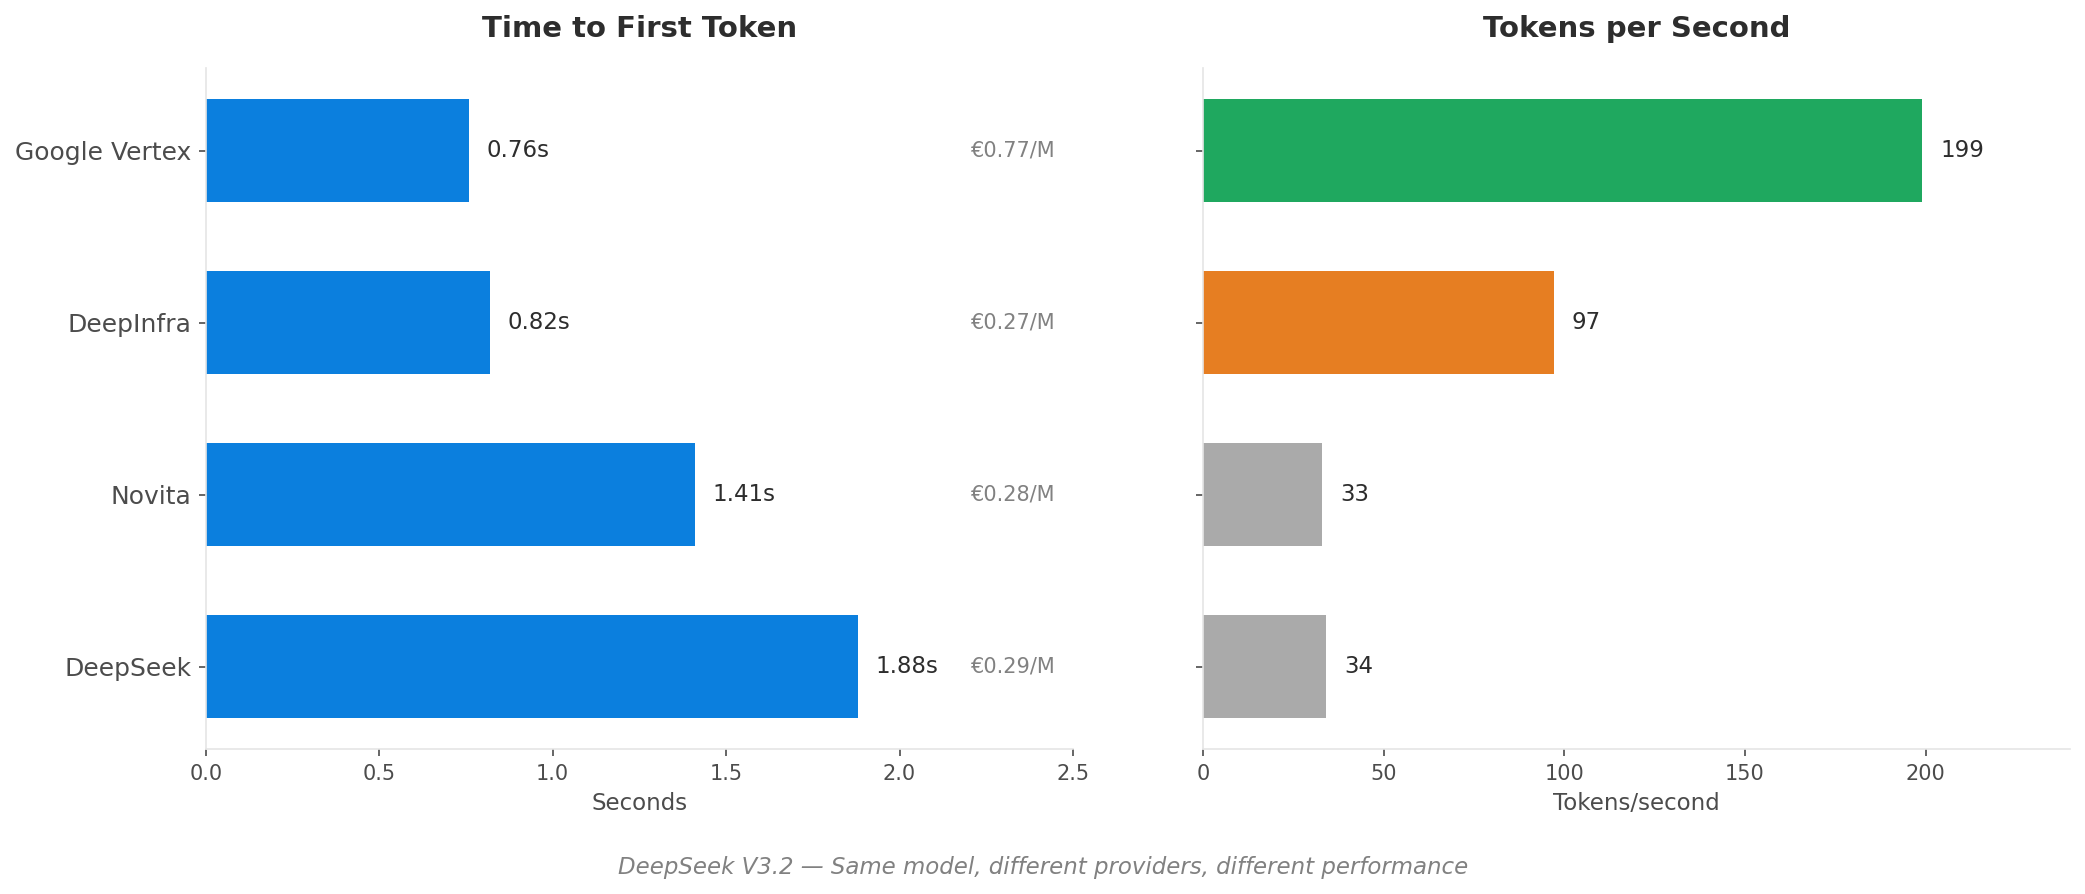
What 'Price Per Token' Doesn't Tell You
If you're comparing AI inference providers by token price alone, you're missing the factors that actually determine cost and performance.